The SecOps platform has had a lot more mathematical analytics capabilities built into it but working with it has its own learning curve, I’ve found. To help with that, I created a new “Stats Hunter” skill:
https://github.com/GooGKush/secops-statistical-hunter
I’ve tried to make the skill work with someone to find the right kind of search, guiding the users to methodologies and choices before generating a multi-stage YARA-L stats search. It also tried to give you guidance on noise thresholds.
For example:
> Using the stats hunter skill, can you help me identify low prevalence domains over the last month?


▸ Thought for 3s, 906 tokens
  Analyzing Query Approaches
  To identify low prevalence domains over the last month using the SecOps Statistical Hunter (secops-statistical-hunter) methodology, we model this threat hunting workflow around
  Fleet-Wide Entity Prevalence (P ≤ 2 internal endpoints) and Query Volume Dispersion over raw telemetry (UDM_EVENTS).
  ──────
  ### 1. Threat Archetype & Statistical Model

  • Threat Archetype: LOW_PREVALENCE_INFRASTRUCTURE / C2_STAGING_DETECTION
  • Telemetry Source: UDM_EVENTS (NETWORK_DNS) (with optional pivot to NETWORK_HTTP / NETWORK_CONNECTION)
  • Mathematical Primitive: Enterprise-wide unique host count P = count_distinct (principal.asset.ip) aggregated per domain over a rolling 30-day window.
  • Hypothesis: Legitimate services (CDNs, OS update servers, major SaaS tools) exhibit high enterprise prevalence (P gg 10 hosts). In contrast, targeted adversary infrastructure
  (stealthy C2 callbacks, staged payloads, spear-phishing destinations) typically resolves on only 1–2 endpoints.
  ──────
  ### 2. Semantic Sensitivity Tiers

  Before running across 30 days of telemetry, select a sensitivity boundary that balances signal coverage against analyst triage capacity:

   Tier                   │ Host Prevalence (P) │ Query Volume Floor / Ceiling │ Physical Interpretation & False Positive Profile
  ────────────────────────┼─────────────────────┼──────────────────────────────┼───────────────────────────────────────────────────────────────────────────────────────────────────────
   CONSERVATIVE           │ P = 1  host         │ 10 ≤ Queries ≤ 500           │ Single-Host Persistent Beaconing: Surfaces domains queried repeatedly by exactly one host. Filters
                          │                     │                              │ out ephemeral one-shot lookups and widespread SaaS.
   BALANCED (Recommended) │ P ≤ 2  hosts        │ 3 ≤ Queries ≤ 500            │ Targeted Infrastructure & Initial Access: Captures staging and C2 callbacks across isolated hosts
                          │                     │                              │ while filtering transient single-packet noise.
   AGGRESSIVE             │ P ≤ 5  hosts        │ Queries ≥ 1                  │ Broad Outlier Sweep: Surfaces every low-volume domain across the fleet. High analyst triage volume;
                          │                     │                              │ includes typos and ephemeral CDN nodes.
   ❌ NOISE CLIFF         │ P > 10  hosts       │ No volume floor              │ Normal enterprise web traffic. Do not hunt at this threshold.
  ──────
Then it gave me some options - both multi-stage and “classic” YARA-L and asked what I wanted to do next. I went with a test probe to help it calibrate
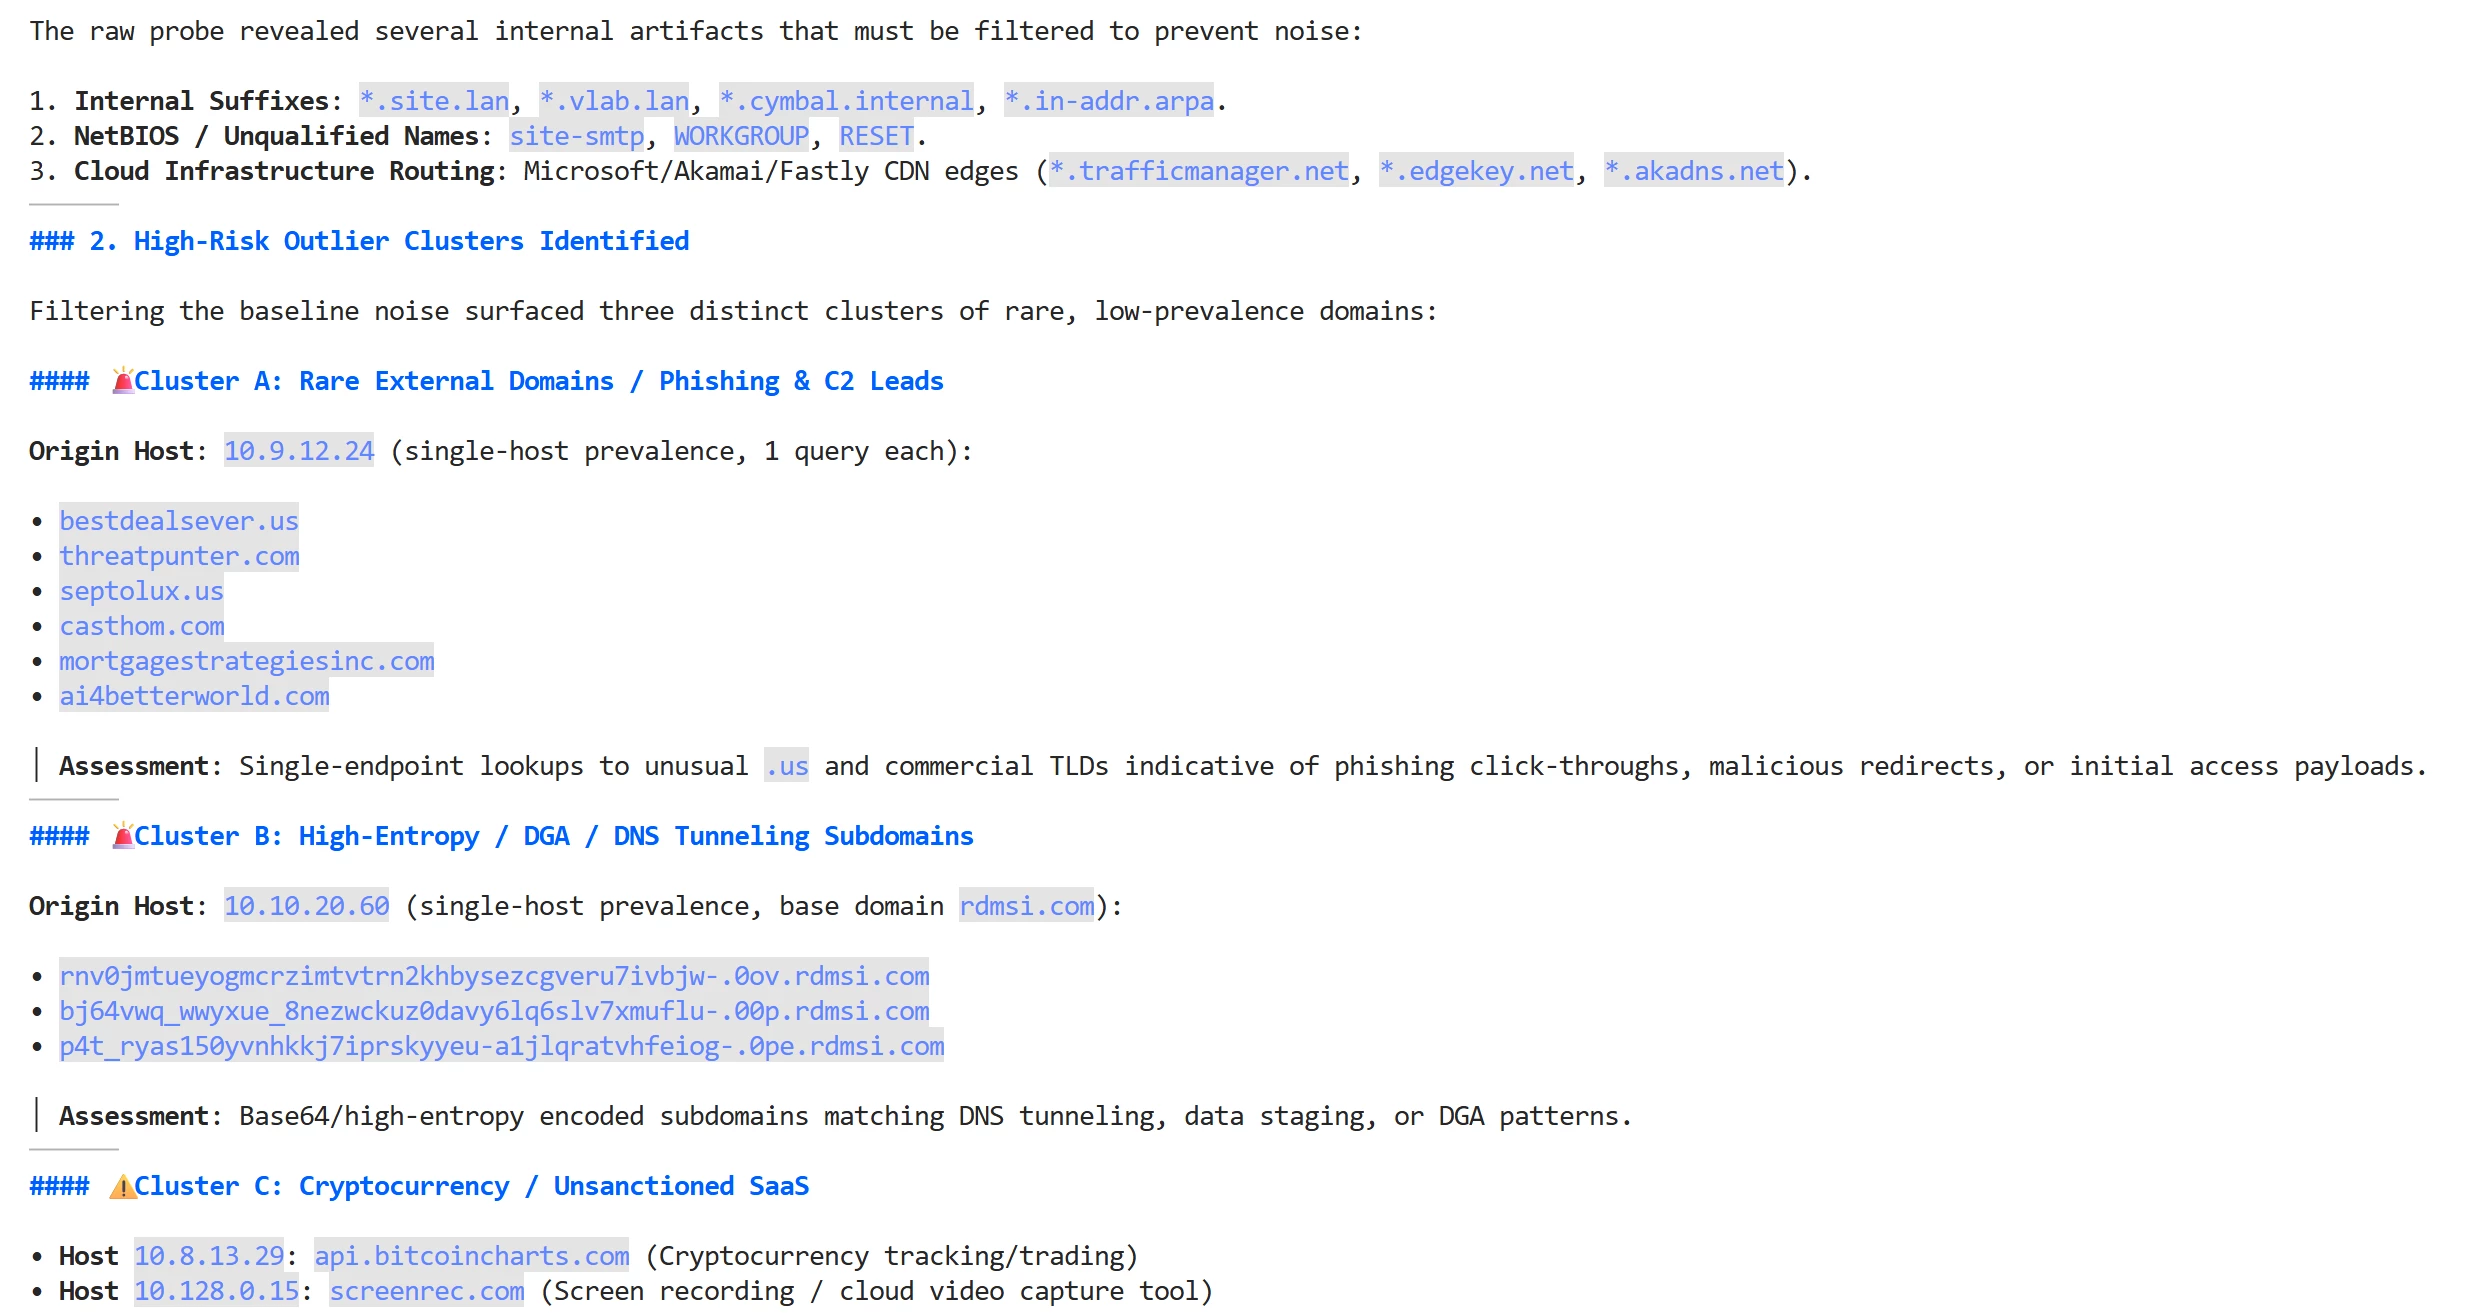
The Skill is designed to help filter out noise and you see it doing that and clustering types of findings:
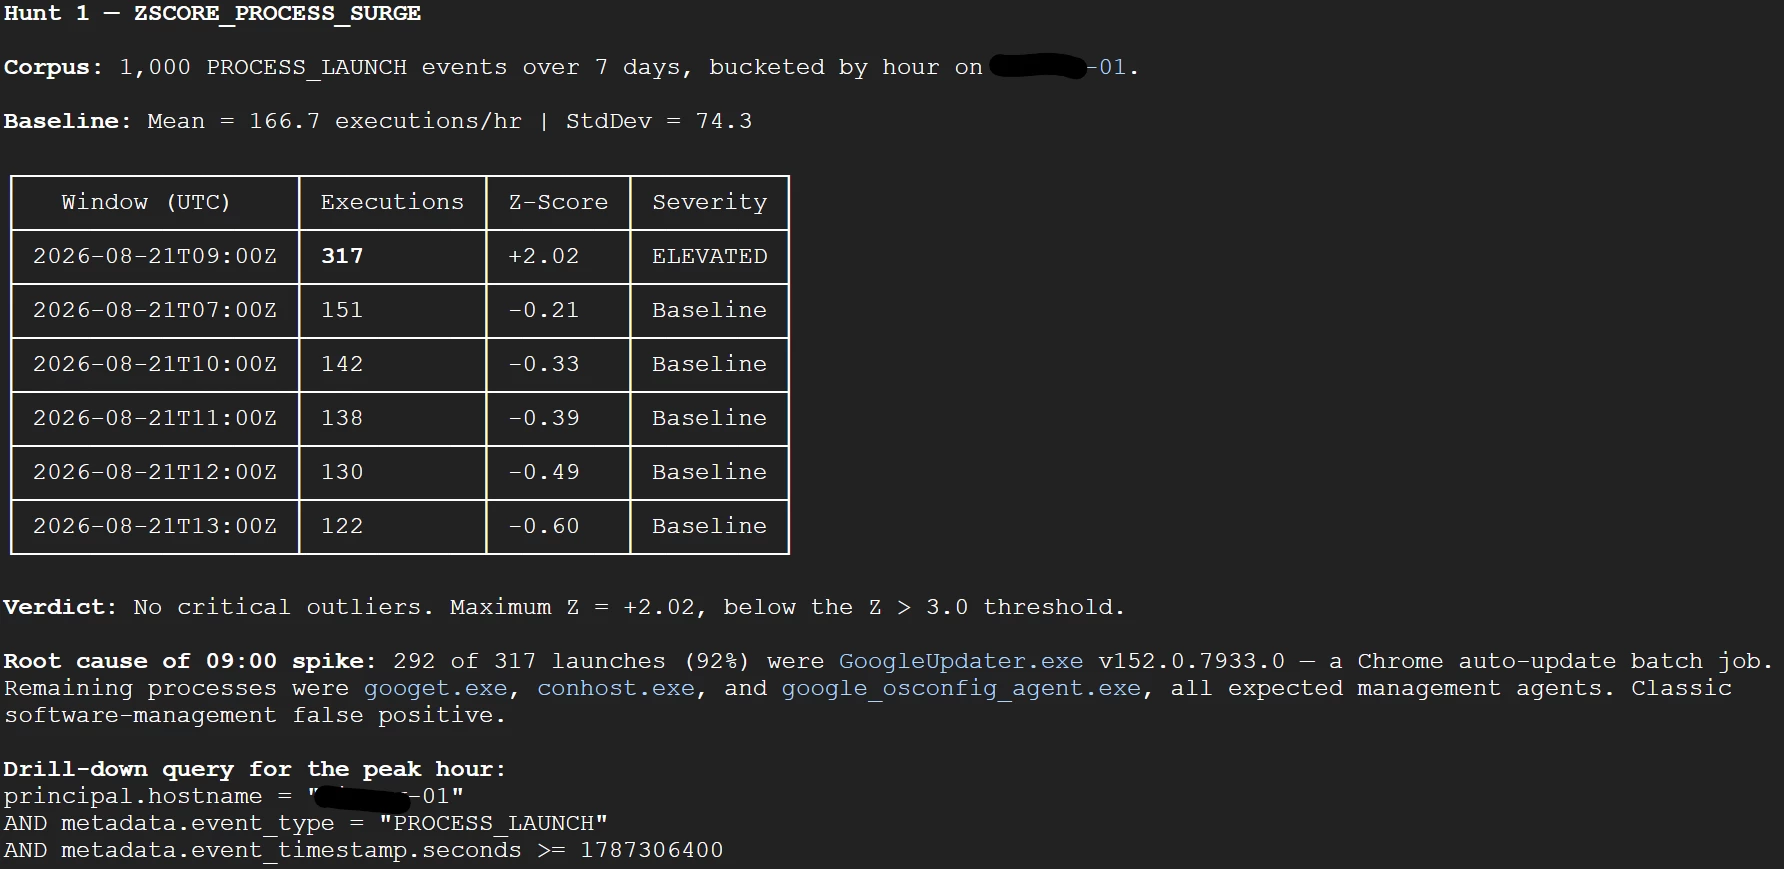
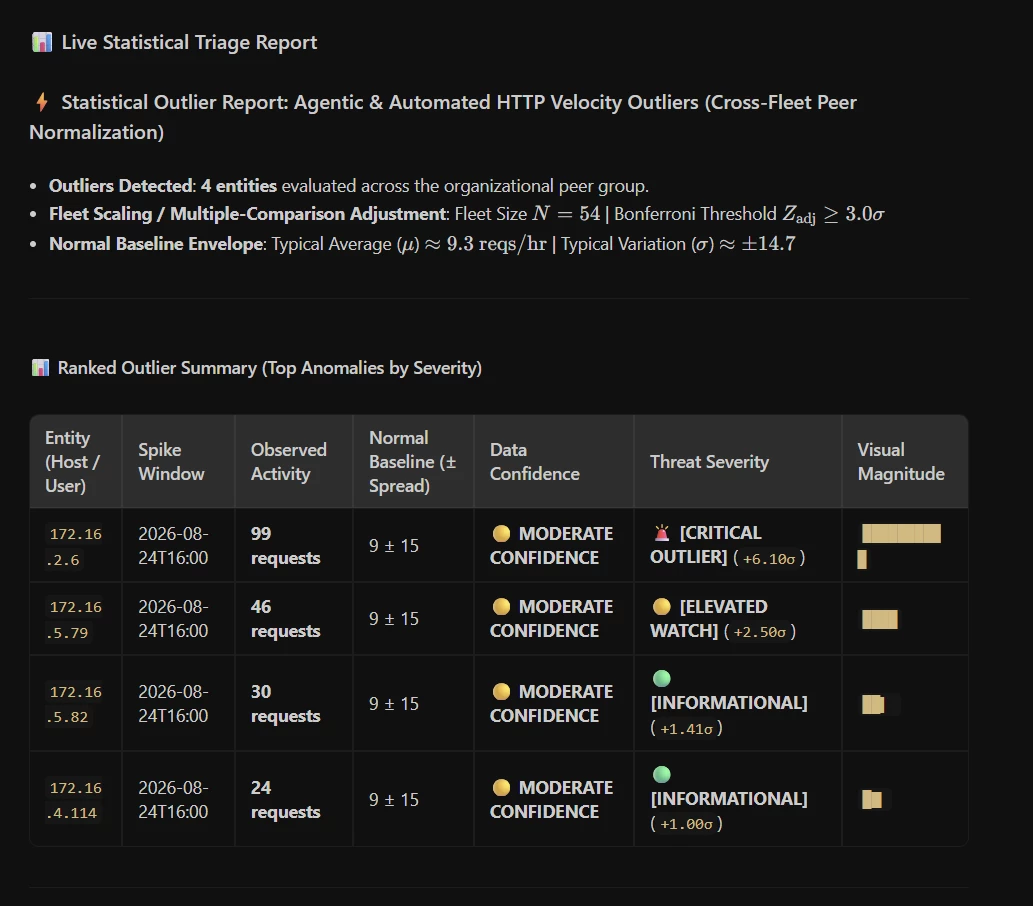
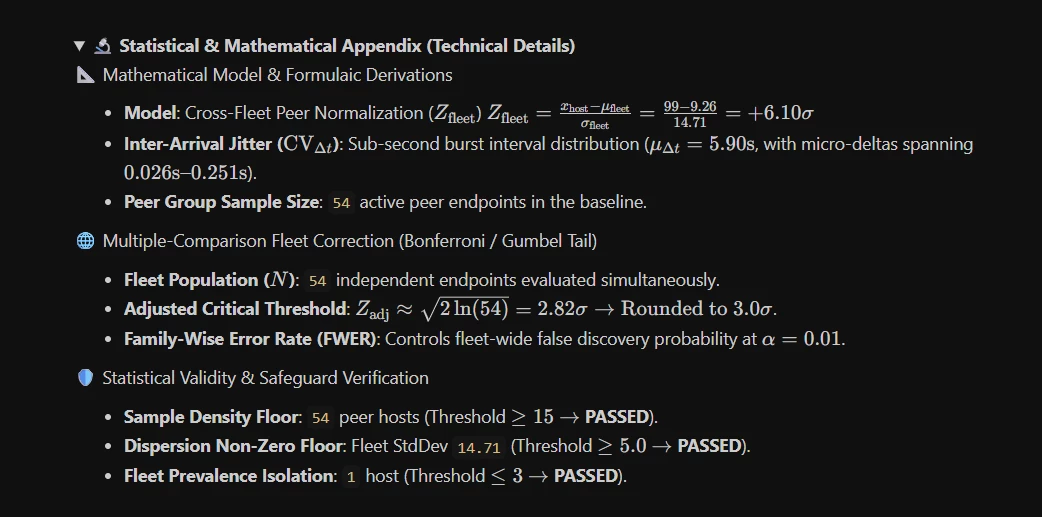
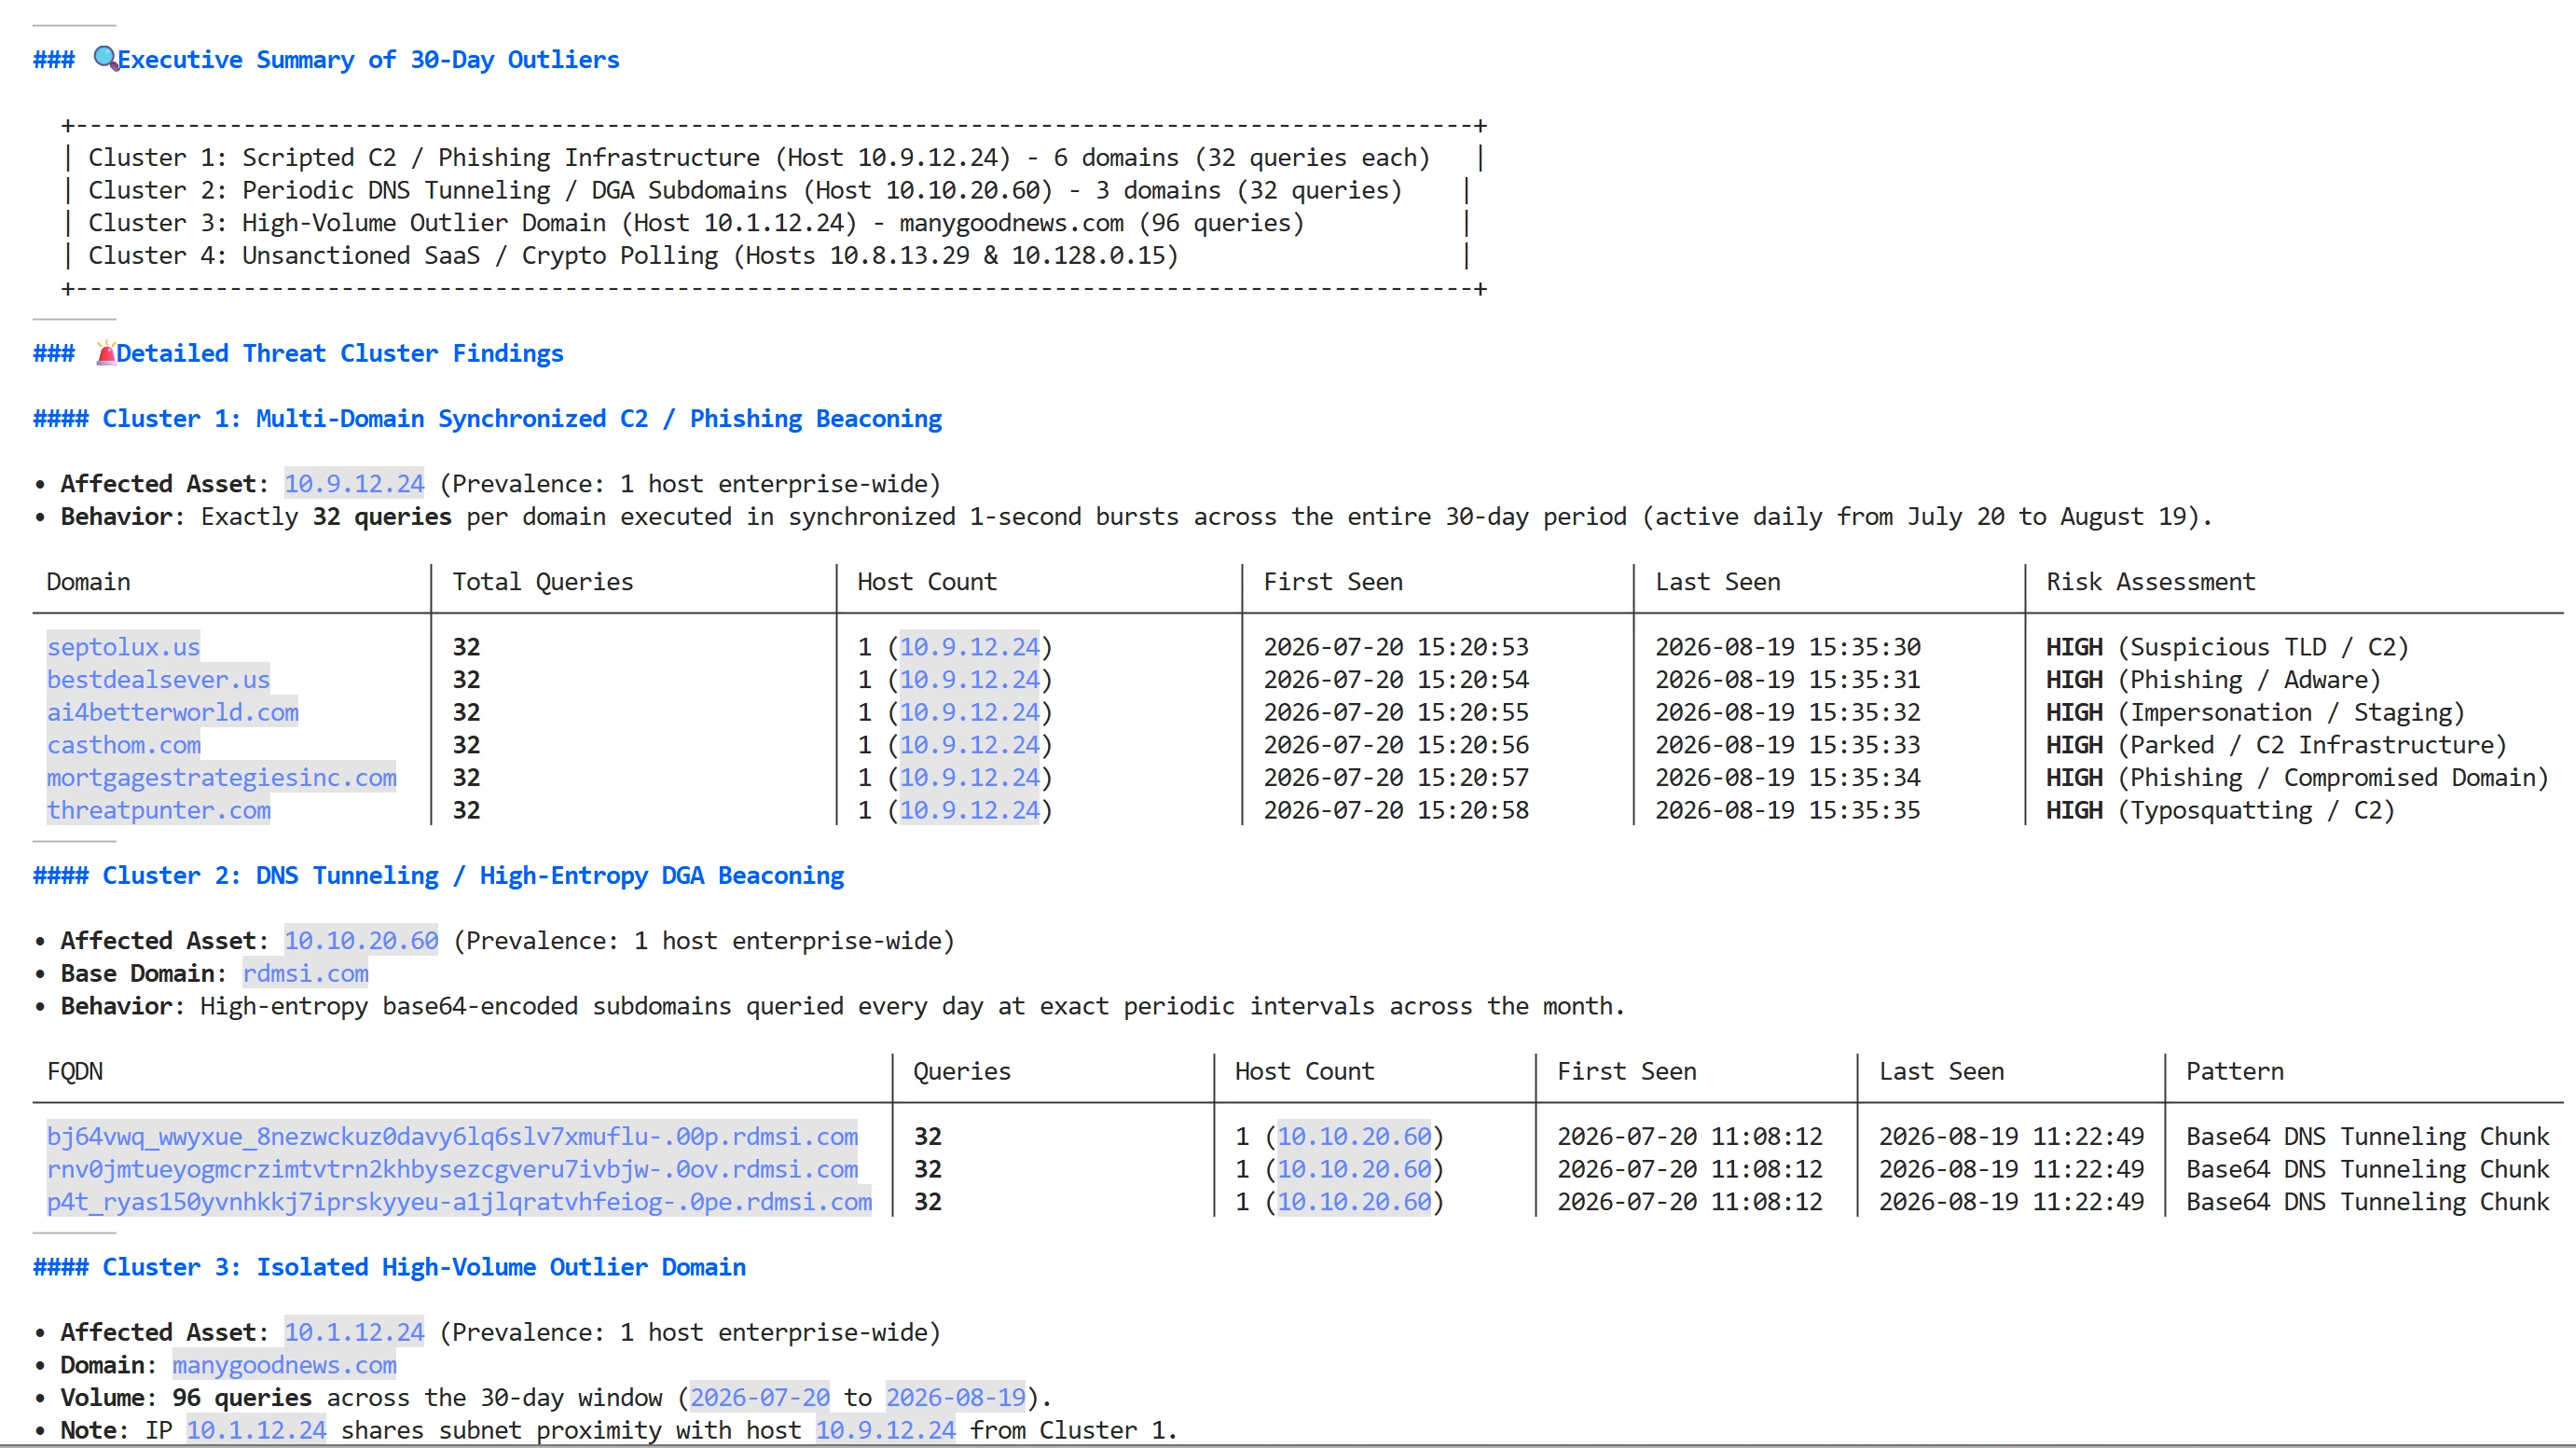
For the output I tried to come up with summary views by default:
Whereas if you’re using an MCP client that supports Javascript graphical renderings, it can generate charts like it did here for a different query:
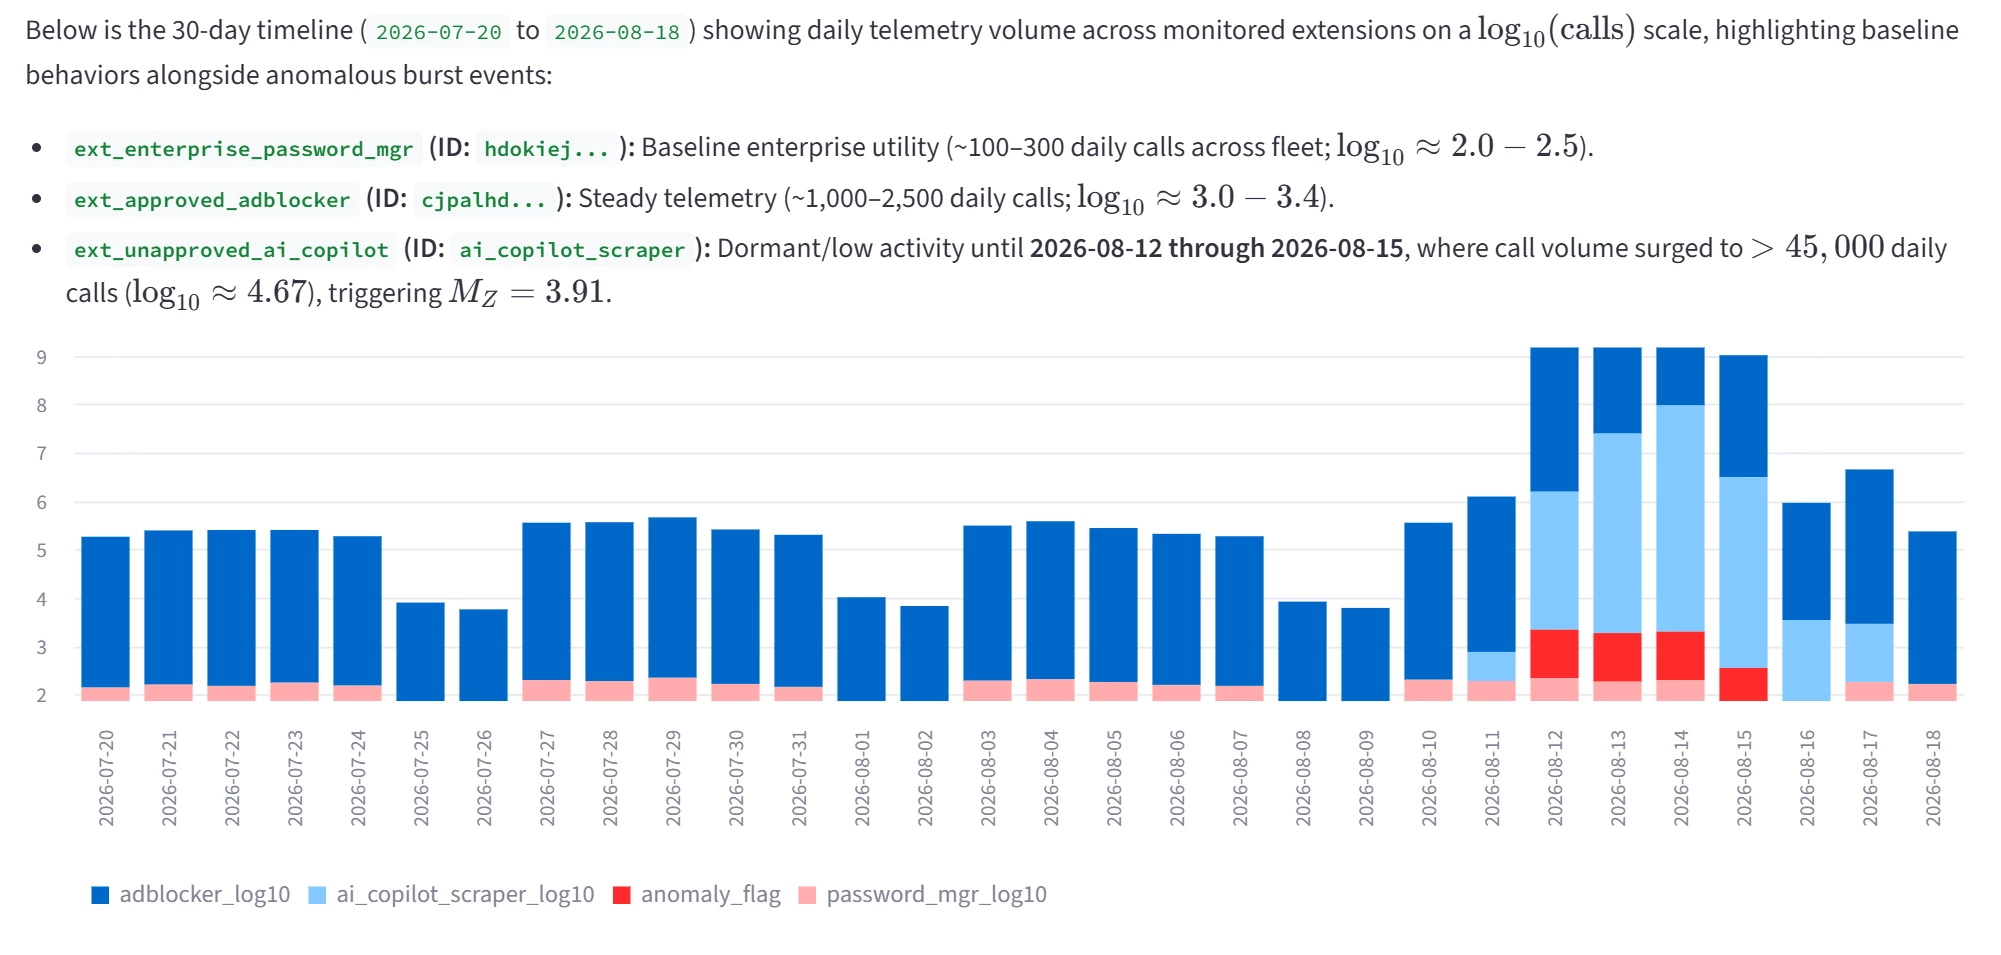
I’ve had some interesting results with broad questions like “Can you help me identify shadow AI in my environment leveraging my EDR and Network logs?”
Please give it a try and let me know how it works out?